Realistic test data with stronger privacy controls
Automated test data pipelines help development and QA teams access realistic data for testing while applying privacy controls to sensitive personal information in lower environments. Improve test quality, strengthen compliance practices, and reduce storage requirements — powered by Redgate TDM.
Solve both problems at once.
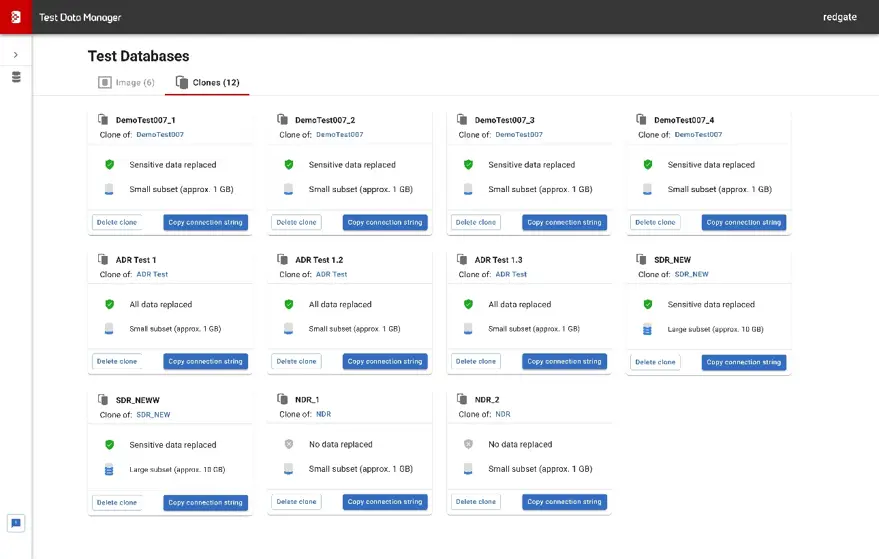
Testing with production data creates regulatory exposure. Unrepresentative or outdated test data can reduce test coverage. Acuative solves both by implementing Redgate Test Data Manager — a platform that automatically discovers sensitive data, masks it consistently, and provisions realistic sub-setted copies into your development, QA, and staging environments at a fraction of the storage cost, integrated directly into your pipeline.
Quality and compliance.
Test with data that reflects production
Poor test data is the hidden cause of defects that make it to production. Acuative configures Redgate Test Data Manager to provision realistic, referentially complete datasets into every lower environment at every test cycle.
Meet regulations without compromising tests
Redgate TDM helps discover, classify, and mask personal data before it is provisioned to non-production environments. Teams get realistic test data while supporting alignment with PDPL, GDPR, HIPAA, PCI-DSS, and internal privacy policies.
Cut storage costs by up to 95%
Full production copies consume enormous storage and backup overhead. Redgate TDM's sub-setting engine provisions only the representative portion each team needs — cutting storage by up to 95% while maintaining referential integrity.
Give teams fresh data — automatically
Acuative integrates Redgate TDM into your CI/CD pipeline so every build, test cycle, or environment refresh can receive a fresh, masked, subsetted dataset automatically — no tickets, handoffs, or manual database copies.
Realistic test data with stronger privacy controls
Redgate Test Data Manager automatically scans your database schema to discover and classify sensitive personal data — so compliance coverage doesn't rely on manually maintained spreadsheets or human intervention.
- Automated column-level scanning using pattern recognition and semantic analysis
- 200+ built-in classifiers covering names, emails, national IDs, financial and health data
- Custom classifier rules for organisation-specific or regional sensitive data types
- Cross-table scanning regardless of column naming conventions
Realistic, compliant substitutes
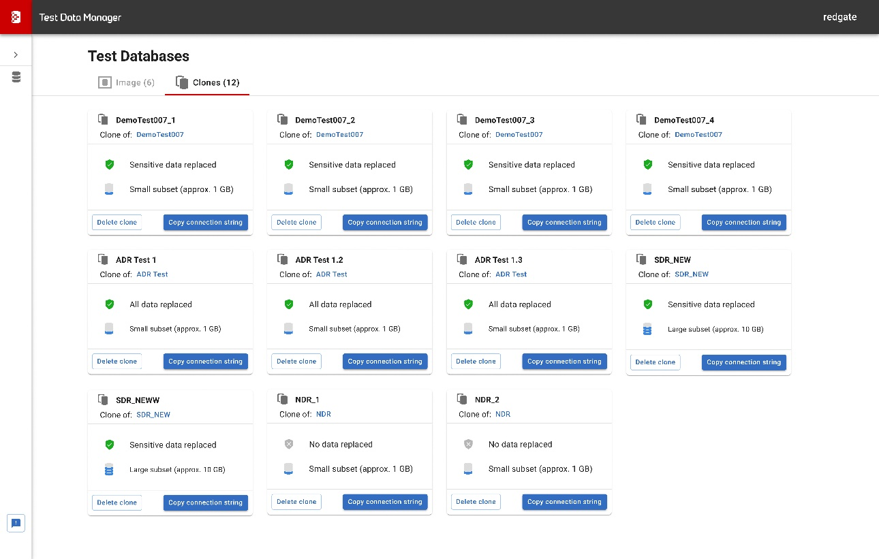
Sensitive data is replaced with realistic, compliant substitutes while maintaining formats, relationships, and referential integrity. Consistent masking ensures the same source value always produces the same masked value — preserving joins and foreign keys.
- Format-preserving masking: IBANs stay IBAN format, IDs stay valid ID patterns
- Deterministic masking: consistent output for the same input across related tables
- Built-in functions: substitution, shuffling, nulling, randomisation, custom expressions
- Production data is never modified — masking applied at provisioning time
2TB down to 100GB
Instead of full copies of production, a statistically representative, referentially complete subset is extracted for testing. A 2TB production database can be reduced to a 100GB test dataset while preserving the relationships and patterns needed for accurate testing.
- Filter rules by date range, customer segment, region, or custom query
- Automatic dependency resolution: related child rows included automatically
- Referential integrity engine: all foreign key constraints satisfied
- Multiple sub-set profiles for unit, integration, and performance tests
Fresh data on demand
Automate test data delivery within CI/CD pipelines, provisioning fresh, masked, and subsetted datasets to development, test, and staging environments on demand or on schedule — without manual intervention.
- Image-based provisioning: masked sub-set saved as a reusable image for rapid cloning
- Clone-on-demand: new test environments spun up from an image in minutes
- REST API integration: provisioning triggered from any CI/CD platform
- Parallel provisioning and automated refresh scheduling
Compliance, continuous.
Compliance Assessment & Discovery
We scan your source databases to identify all sensitive data fields and map results against PDPL, GDPR, NCA, SAMA — producing the complete masking specification that forms your implementation's foundation.
Masking Rule Configuration
We configure masking functions for every classified field — format-preserving, deterministic, or custom — and validate referential integrity across all foreign key relationships before any provisioning runs.
Sub-Setting Profile Design
We design sub-setting profiles for each team and environment type — unit, integration, performance — configuring filter logic, dependency resolution, and size targets, validated with a full referential integrity check.
Pipeline Integration
We integrate provisioning into your CI/CD workflow — automated image refresh, on-demand cloning for developer environments, and environment metadata tracking for test run traceability.
Ongoing Compliance Maintenance
As your schema evolves — new tables, columns, data categories — we maintain your masking ruleset so no new sensitive fields are left unmasked, with periodic scans and compliance coverage reports.
Questions, answered.
Redgate Test Data Manager uses format-preserving masking — real values are replaced with realistic substitutes in the same format. Names become valid names, emails become valid emails, IDs stay in the correct pattern. Tests behave identically to production, so you catch the same defects without the compliance risk.
Sub-setting provisions a representative portion of production data — rather than a full copy — while maintaining all relationships and patterns needed for accurate testing. Most organisations see 80–95% storage reduction. Acuative configures the logic so each team gets exactly what they need.
Automated masking and classification documentation directly support PDPL (Saudi Arabia), GDPR (EU), HIPAA, and PCI-DSS. Acuative configures masking rules to align with your specific obligations and produces the audit documentation your compliance team requires.
Yes. Acuative integrates Test Data Manager via its REST API into your CI/CD platform of choice — Azure DevOps, GitHub Actions, GitLab CI, Jenkins, and others. Every build or test cycle automatically receives a fresh, masked, sub-setted dataset.
As part of Acuative's managed support, we conduct periodic classification scans to identify new sensitive fields introduced by schema changes. Your masking ruleset is updated before those fields reach a lower environment — so compliance coverage is continuous, not a one-time exercise.

